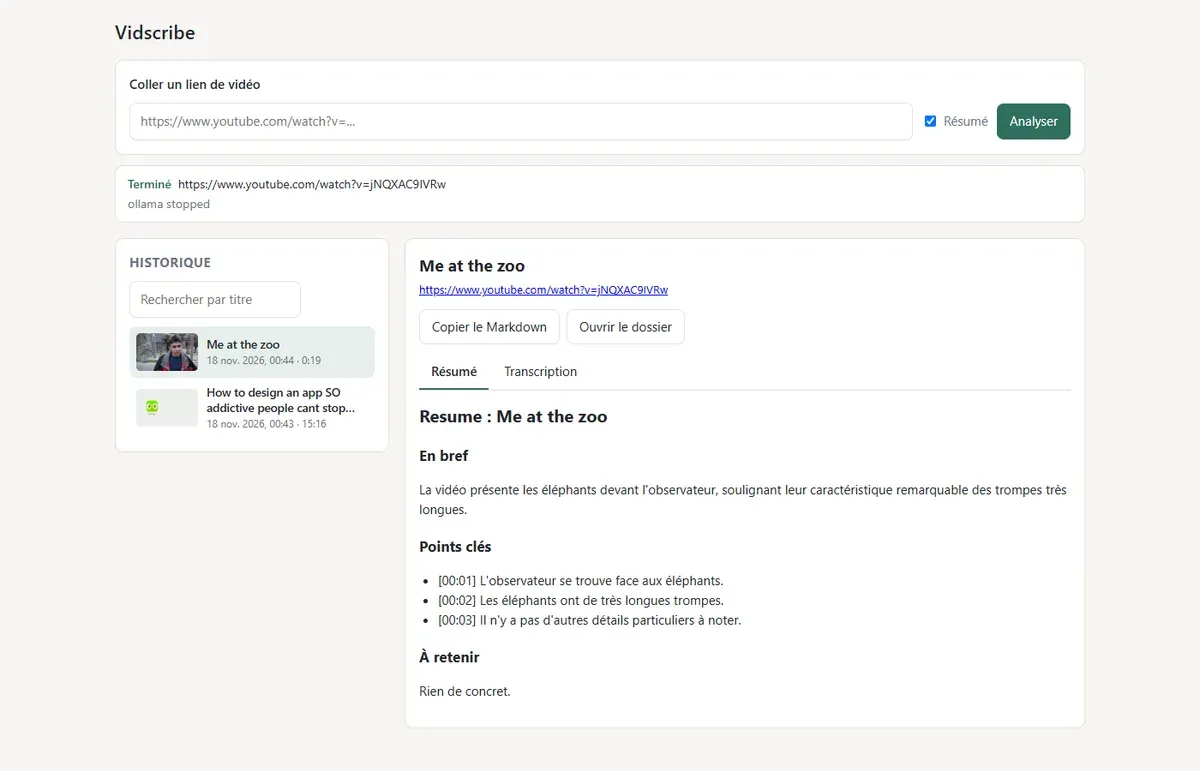
Vidscribe
A tool that turns a video, a YouTube link or a file, into a single timestamped Markdown document: what is said and what is on screen, in a form an AI can read.
- Ongoing
- Python
- CUDA
- Ollama
- Claude Code
A language model does not watch a video. Vidscribe hands it the content as text: what is said and what is shown, brought together in one Markdown file split into one-minute blocks.
The video is downloaded with yt-dlp. When it has subtitles, they are used; otherwise the audio is transcribed on the machine with faster-whisper, on the graphics card when one is available. Alongside, ffmpeg detects scene changes and samples key frames at regular intervals, and a local vision model, served by Ollama, describes each one. The descriptions are inserted into the transcript at the moment the frame appears.
A three-part summary (in short, key points, takeaways) can be added, written by Claude when it is installed, otherwise by a local model. Frame descriptions can be wrong: the frames stay linked from the document so they can be checked.
The tool runs from the command line or through a small local window: paste a link, get the transcript and summary, and a history keeps the videos already processed. The code is not published.
Private project, no public link